Publications
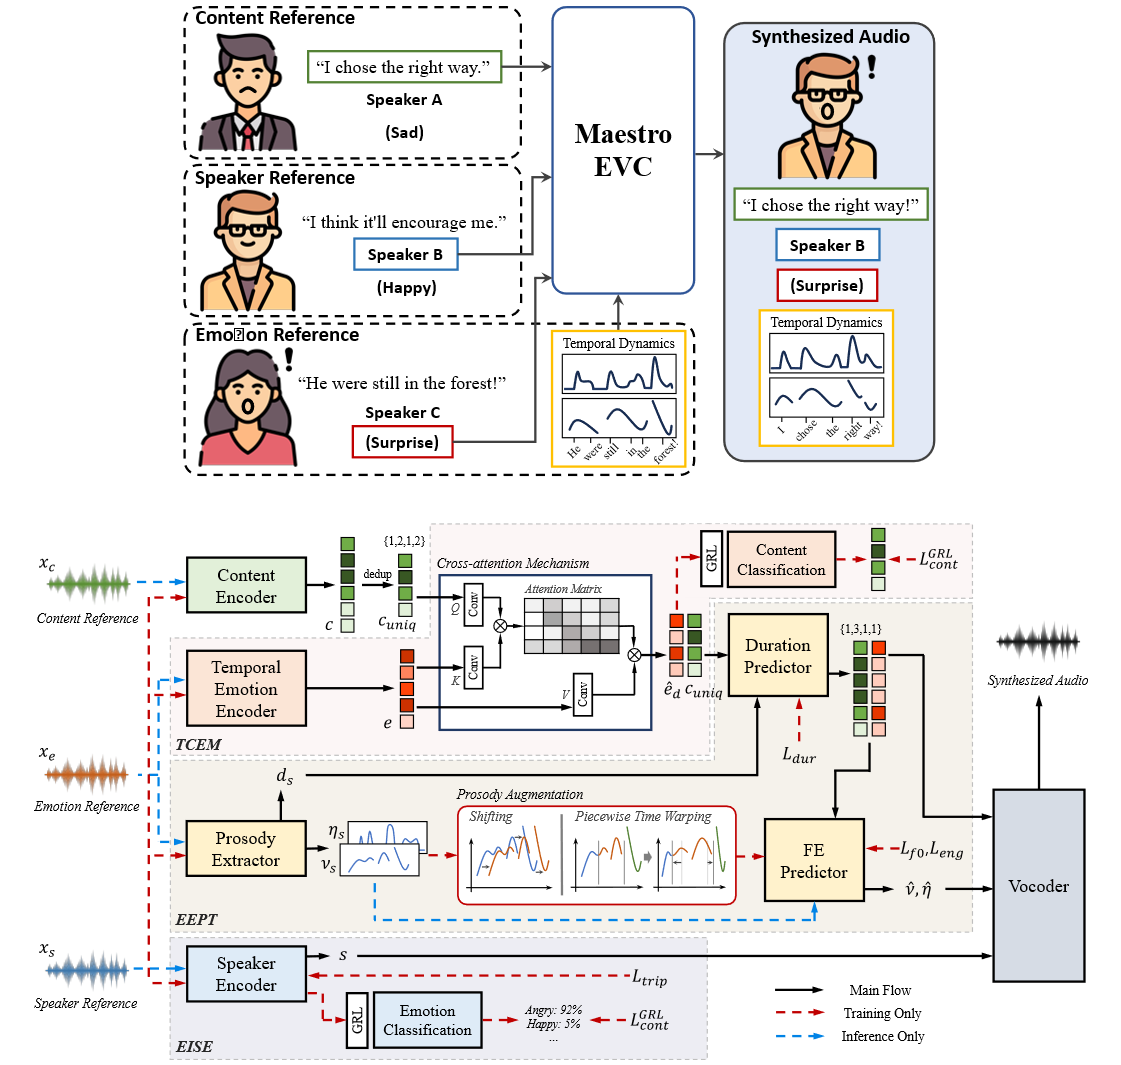
Maestro-EVC: Controllable Emotional Voice Conversion Guided by References and Explicit Prosody
Emotional voice conversion (EVC) aims to modify the emotional style of speech while preserving its linguistic content. In practical EVC, controllability, the ability to independently control speaker identity and emotional style using distinct references, is crucial. However, existing methods often struggle to fully disentangle these attributes and lack the ability to model fine-grained emotional expressions such as temporal dynamics. We propose Maestro-EVC, a controllable EVC framework that enables independent control of content, speaker identity, and emotion by effectively disentangling each attribute from separate references. We further introduce a temporal emotion representation and an explicit prosody modeling with prosody augmentation to robustly capture and transfer the temporal dynamics of the target emotion, even under prosody mismatched conditions. Experimental results confirm that Maestro-EVC achieves high-quality, controllable, and emotionally expressive speech synthesis.
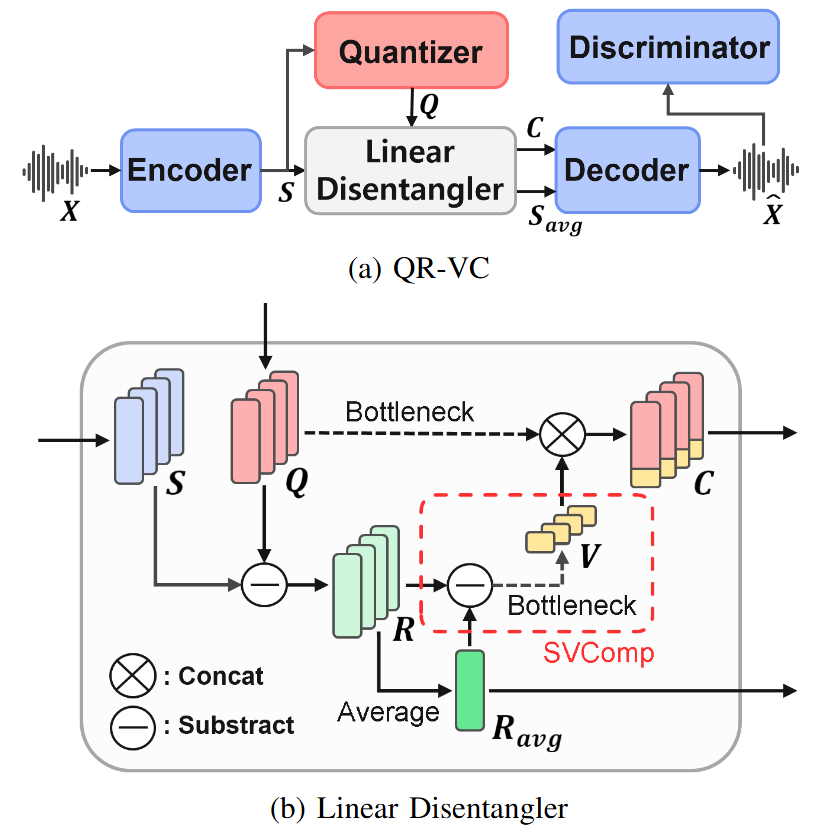
QR-VC: Leveraging Quantization Residuals for Linear Disentanglement in Zero-Shot Voice Conversion
Zero-shot voice conversion is a technique that alters the speaker identity of an input speech to match a target speaker using only a single reference utterance, without requiring additional training. Recent approaches extensively utilize self-supervised learning features with K-means quantization to extract high-quality content representations, effectively removing speaker identity by exploiting their structural properties. However, this quantization process also eliminates fine-grained phonetic and prosodic variations, leading to degradation in intelligibility and prosody preservation. While prior works have primarily focused on quantized representations, the potential of quantization residuals remains underexplored. In this paper, we introduce a novel approach that fully utilizes quantization residuals to disentangle speaker identity while restoring phonetic and prosodic details lost during quantization. By applying only K-means quantization and linear transformations, our method achieves effective disentanglement within a unified framework. This enables high-fidelity voice conversion while relying solely on reconstruction losses, eliminating the need for explicit supervision. Furthermore, it removes the reliance on complex, deep networks in the disentanglement structure. Experiments demonstrate that the proposed model outperforms existing methods while maintaining a simple disentanglement structure. It achieves superior intelligibility and speaker similarity while better preserving prosody, highlighting the impact of quantization residuals in zero-shot VC.
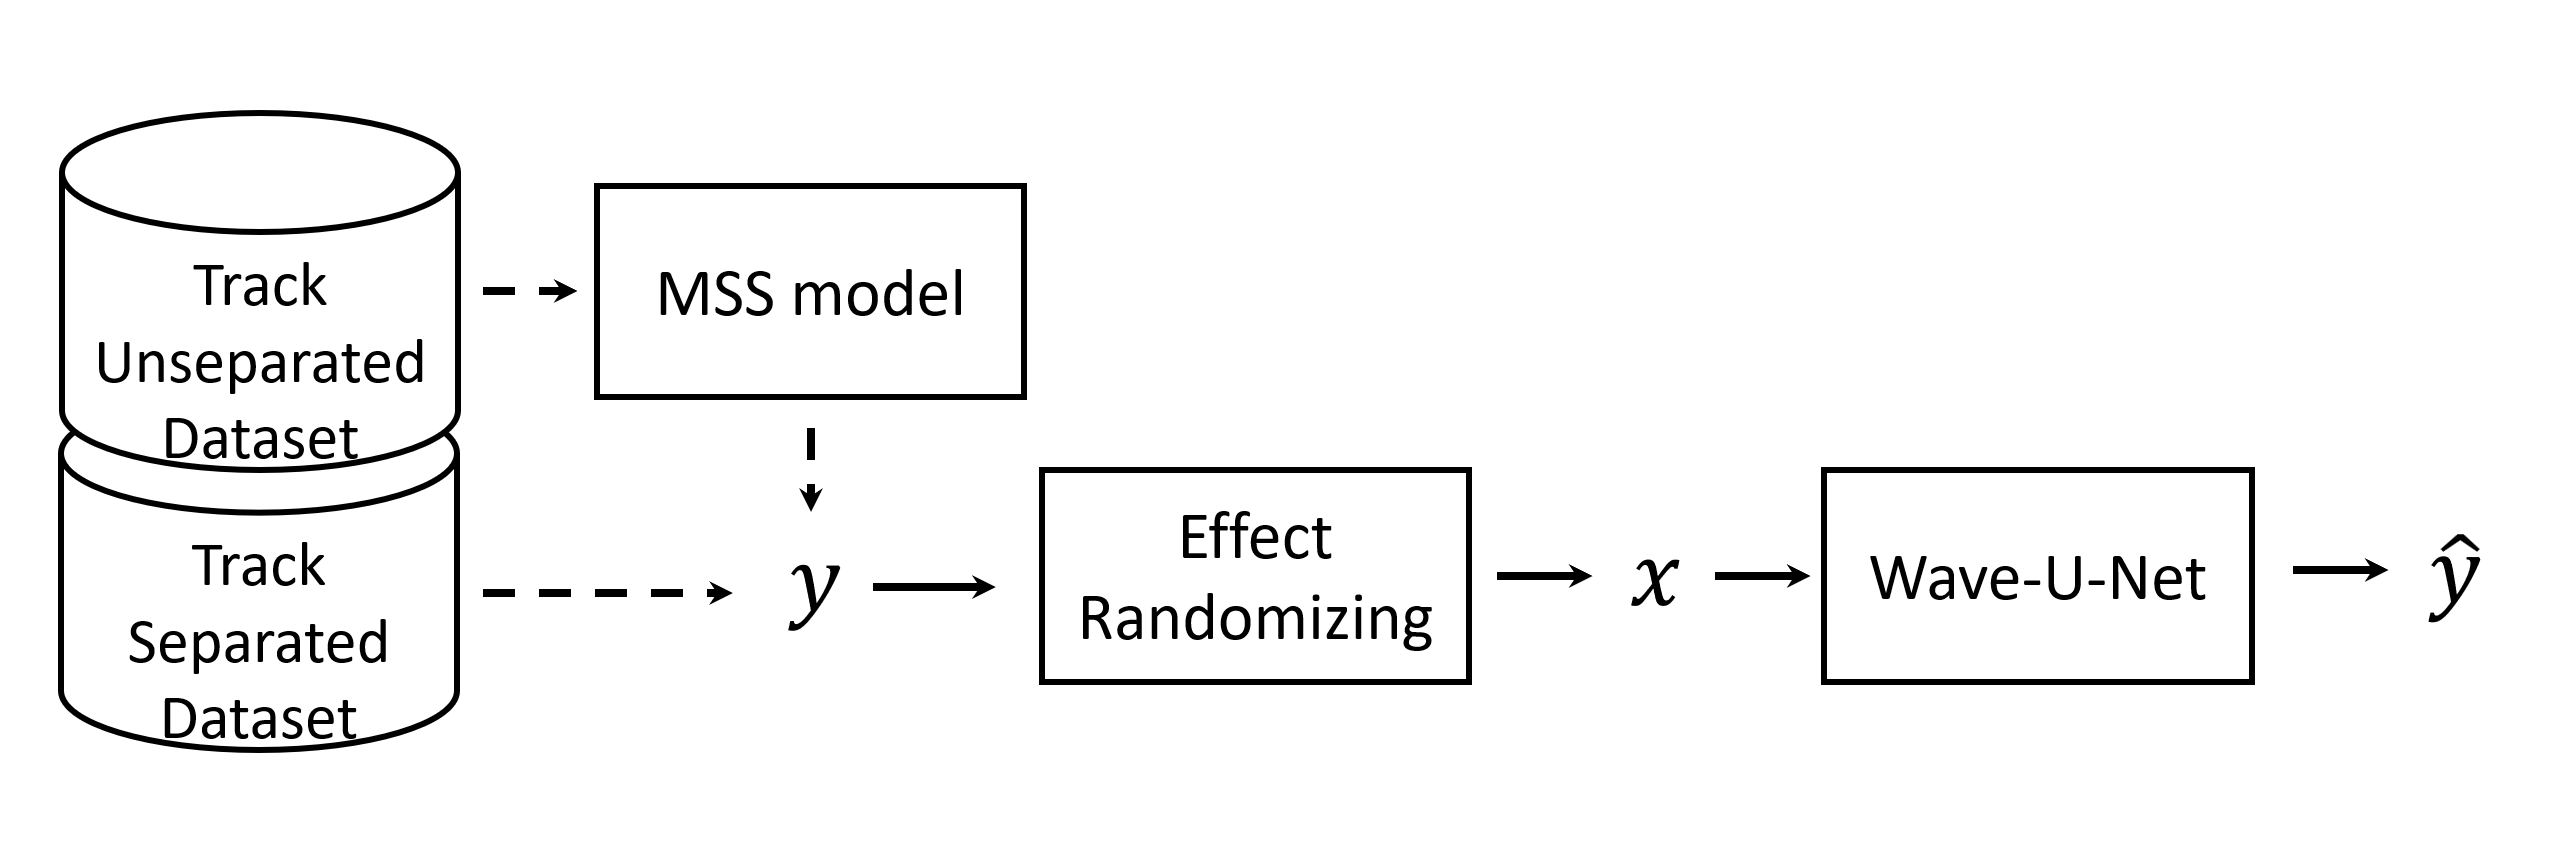
Automatic Music Mixing Using Music Source Separation Models and Wave-U-Net
Music mixing refers to the process of recording individual tracks of instruments and refining them using expert knowledge to blend them appropriately. In recent years, there has been research into automated music mixing utilizing deep learning; however, the lack of dry recording data with individual track recordings and mixing has limited the performance of such models. In this study, we address the data scarcity issue by employing music source separation models to extract individual track recordings and generate recordings with randomly adjusted volumes. Subsequently, we train a Wave-U-Net-based automatic music mixing model to design an automated music mixing system.